When adopting AI coding while keeping source code under internal control, the first thing to decide is "which workloads run where, and what information can be transmitted." Self-hosting the agent execution infrastructure and confining model inference entirely within internal networks must be architected as separate concerns.
Correction on September 17, 2026: We revised descriptions from the earlier version implying that tools like Claude Code were directly bundled, as well as claims that self-hosting alone eliminates external code transfers. We also removed guarantees regarding audit compliance and unsubstantiated comparisons of implementation timelines and costs.
Below is an overview of the architecture based on Coder's current official documentation (v2.37) reviewed on the same day. This first part covers official specifications and key verification items during setup. The results of running Coder and a local LLM on a Mac are compiled in our hands-on testing follow-up article. It features actual screenshots demonstrating code modifications, test execution, and behavior when the model stops. Testing full traffic metrics and audit requirements was not performed in the follow-up either.
What runs where in Coder Agents
According to the official overview, Coder Agents uses its own agent implementation to execute agent operations within Coder's control plane. It is not a wrapper that packages and runs Claude Code or Codex. Its role should be considered separately from setups where IDEs or other coding tools are used inside Workspaces.
To understand the architecture, track the following three locations.
| Location | Primary role | What to verify during implementation |
|---|---|---|
| Coder control plane | Processing conversations, requesting model inferences, and delegating tool executions | Connection destinations, credentials, stored data, and administrator permissions |
| Workspace | Reading and writing files, running commands, builds, etc. | Readable repositories, execution permissions, and network restrictions |
| LLM inference destination | Receiving requests and returning model responses | Operating entity, transmittable information, and retention/usage terms |
According to the official architectural documentation, the flow involves the control plane forwarding conversations to the configured LLM, running processes in the Workspace as necessary, and returning those results to the model. Even if the Workspace does not connect directly to the LLM, you must verify network traffic from the control plane to the inference destination.
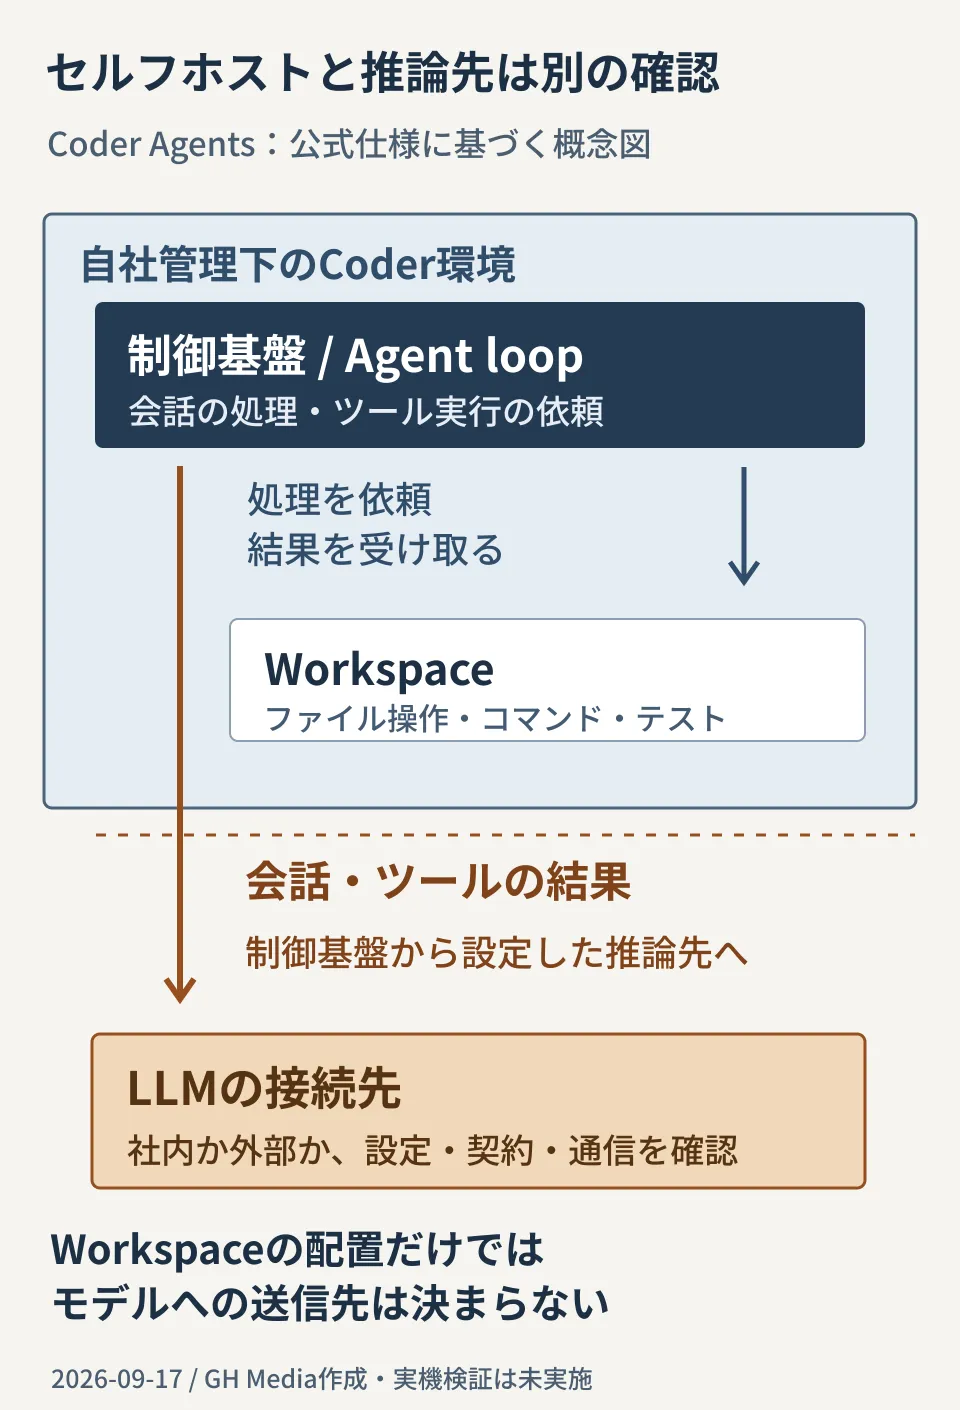
This diagram is a conceptual representation based on official specifications, not a measurement diagram from an environment run by GH Media. The key takeaway is that the location of the Workspace alone does not dictate where information sent to the model travels.
Turning "keeping code inside the company" into verifiable requirements
Directly substituting product names for a requirement like "do not let data leave the company" blurs verification. At a minimum, you must define which data—among code contents, prompts, command outputs, errors, logs, etc.—can be sent and where. Content read by tools that ends up in model inputs must be handled under the same rules.
Approaches can be categorized as follows.
- Architectures allowing transmission to external LLMs: Verify the scope of transmitted information, contractual terms of use, and retention/access policies.
- Architectures using internal inference destinations: Verify target model and API compatibility, and inspect other outbound traffic originating from the control plane and Workspaces.
- Architectures routing through proxies or gateways: Trace not only intermediary points, but also the final inference destination and the data processed there.
This is a classification for organizing requirements. This article does not demonstrate the behavior or network isolation of each architecture. Whether a dedicated cloud environment satisfies internal requirements must also be evaluated by factoring in connection, operational, and contractual conditions rather than location country alone.
According to official model configuration documentation, providers and compatible endpoints can be configured. However, simply being able to save a URL does not confirm that the destination supports the APIs or tool calling used by Coder. Verification using actual requests and responses is necessary.
Implementation components in client projects
Before combining products, determine who will verify what. The following is a checklist for architecture evaluations, not a pre-validated product bundle.
| Area under evaluation | Items to verify |
|---|---|
| Control plane and Workspaces | Deployment location, update procedures, backups, and network connection routes |
| Model connectivity | Authentication, API compatibility, destinations, and available models |
| Identities and execution permissions | Whose authority is used to read repositories, modify files, and execute workloads |
| Network | Allowed destinations for the control plane and Workspaces, including package downloads and external tools |
| Logs and conversation data | Whether required records can be captured, viewing permissions, retention periods, and deletion/recovery methods |
Distinguish between conversations being saved and meeting the audit trail requirements demanded by an organization. Decide which elements are needed among "actor," "target modified," "execution timestamp," and "content sent to model," and inspect the actual system to see what can be retrieved. Retention periods and costs cannot be determined uniformly by product names alone.
What to verify first when starting with a small-scale trial
The quickstart guide outlines prerequisites such as LLM provider and model settings, administrative privileges, and Workspace templates. Once preparations are complete, create a plan to test using a non-confidential test repository.
An ideal first task is something whose results can be verified by a human, such as "fixing a small function and running its tests." Record the following during verification:
- Environment and configuration: Coder version, model identifier, connection destination, template used, and task input.
- Actual results: Modified files, executed commands, test outcomes, and actions that failed midway.
- Destination of data: Connections from the control plane and Workspaces, and the extent to which content sent to models can be verified.
- Permission boundaries: Inability to access unauthorized repositories or actions, and whether intended restrictions actually take effect.
- Operational verification: Shutdown methods, error tracing, log viewing, and items to re-check after updates.
Only after verifying these points can you explain what was accomplished under those specific conditions. A single successful test does not prove enterprise-wide security, productivity gains, or compatibility across all models.
Information to assemble before making an adoption decision
The starting point of any evaluation consists of target workflows, handled data, allowable inference destinations, required permissions, and audit logs to preserve. Based on those criteria, determine whether to use existing infrastructure, integrate Coder, or explore alternative architectures. Implementation timelines and costs should be estimated only after target user counts, existing platforms, and operational requirements are established.
If you are at the stage of "wanting to clarify how much internal code and data can be transmitted" or "needing to define verification criteria to compare adoption candidates," please reach out via our inquiry form with your current architecture and constraints.