Open an estimate you received six months ago. If it involves a system incorporating AI features, you should see a line item for "AI Usage Fees (Estimated Monthly)." Recalculating that figure with current rates may reveal that it has dropped to a fraction of the original cost.
While this appears to be welcome news, its practical implication is different: running cost assumptions shifting within six months means the business rationale behind internal approval and ROI calculations becomes obsolete at the exact same pace.
What changed on July 30, 2026
OpenAI updated pricing across the GPT-5.6 family, cutting rates for the mid-tier Terra model by 20% and the small Luna model by 80% (OpenAI drops GPT-5.6 Luna and Terra API prices by up to 80% — InfoWorld).
| Model | Prior pricing (per 1M tokens) | After Revision |
|---|---|---|
| GPT-5.6 Luna | Input $1 / Output $6 | Input $0.20 / Output $1.20 |
| GPT-5.6 Terra | Input $2.50 / Output $15 | Input $2 / Output $12 |
Concurrently, a "Fast Mode" was introduced for the flagship Sol model. Priced at twice the standard rate (Input $10 / Output $60), it is positioned to deliver up to 2.5x faster processing speeds without compromising model capability (Advancing the price-performance frontier with GPT-5.6 — OpenAI).
While smaller models became five times cheaper, a mechanism was introduced to pay a premium for speed. The accurate takeaway is not that prices fell across the board, but that the dimensions of choice expanded.
Do not stop at "it's cheaper, so we're safe"
There are three points clients need to verify here, each tying directly to how you interpret cost estimates.
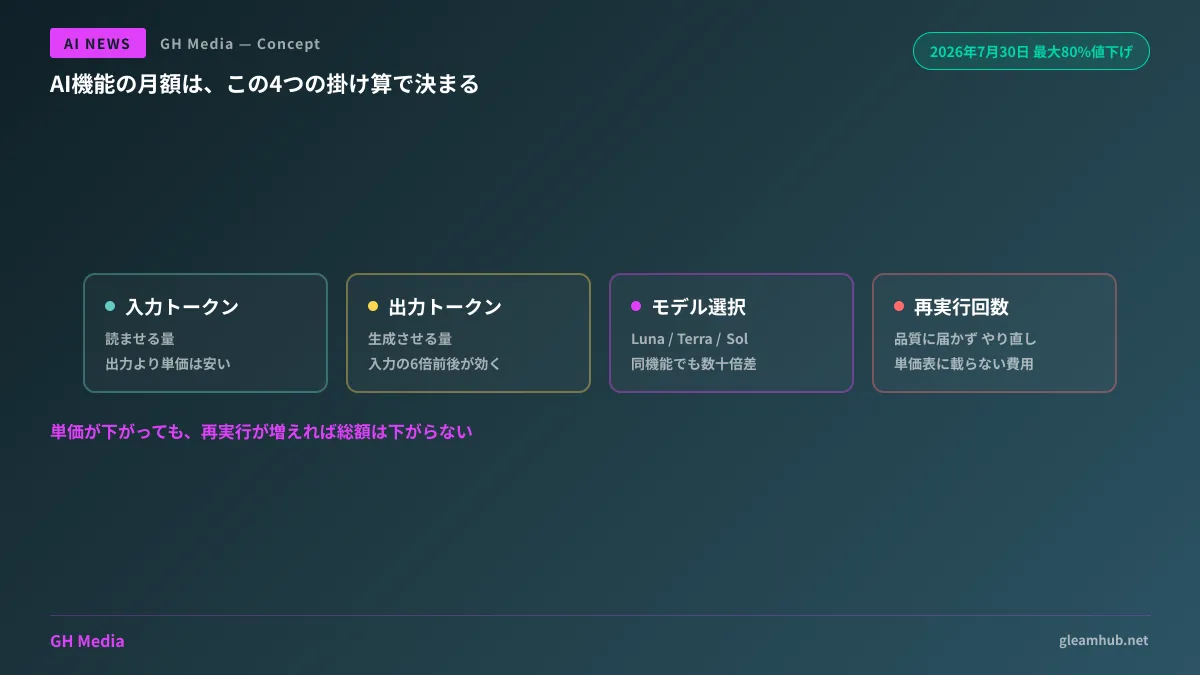
First is the unit cost of output. Looking at the table, output pricing across all models is set roughly six times higher than input. This structure remained unchanged after the price cut. In other words, features generating longer text have a much greater impact on costs. Summarizing internal documents (long input, short output) versus generating proposal drafts (short input, long output) produce opposite cost profiles despite both being labeled "AI features." If an estimate lumps this into a single "AI Usage Fees" line item, ask which usage pattern was assumed.
Second is which model forms the baseline of the estimate. For the identical feature, building on Luna versus Sol can shift unit costs by dozens of times. If the estimate omits specific model names, verifying that cost is impossible.
Third is whether price cuts actually pass through to your company. In custom development contracts, AI usage charges are handled either as "actual expenses + management fee" or bundled into a fixed monthly fee. In the latter case, your invoice will not decrease even if API rates fall. This is not a matter of right or wrong, but an arrangement that must be defined during contracting. The dynamic is identical to CI expenses being passed onto maintenance fees, and the verification method outlined in When the Reason for a Maintenance Fee Increase Was "Surging CI Costs" applies directly.
Defaulting to cheaper models can inadvertently increase costs
Concluding that "since Luna is five times cheaper, we should use Luna for everything" often backfires.
The underlying culprit is reruns. If output fails to meet quality standards, human operators must refine instructions and execute the prompt again. Even if single-run unit costs are one-fifth, having to rerun three times makes actual costs triple. Furthermore, the human labor spent reviewing and reworking never appears on API rate cards.
The logical evaluation sequence should proceed as follows:
- Define the required accuracy threshold upfront. Is this a workflow where human review can correct mistakes, or one where output goes directly to external parties?
- Test smaller models on workflows with human review. Summarization, classification, and drafting initial outlines frequently fit here
- Budget for advanced models when outputs are client-facing or guide critical decisions
- Measure actual rerun rates following deployment. If rates exceed assumptions, the model selection is incorrect
Only after executing through step four do rate sheet figures align with real-world expenditures. Criteria for adoption decisions across model generations are detailed in GPT-5.5 Released: 4 Perspectives for Adoption Decisions in Client Projects, and the logic applies directly here.
Business requirements dictate whether Fast Mode is worth paying for
Sol's Fast Mode charges a 2x premium for speed rather than intelligence. While this looks like an engineering choice, it is fundamentally a business requirement.
When users wait actively on screen, speed defines the user experience. In automated contact form responses or search tools queried live by sales reps during meetings, slow responses result in abandonment.
Conversely, for overnight batch jobs or features where users return later to review results, paying extra for speed makes no sense. Even within the same system, the right choice differs by feature. Nodding reflexively when asked "would you prefer it faster?" means paying a 2x rate for tasks where nobody is waiting.
Count this one item before opening the estimate
There is just one action to take: verify how much the AI features were actually utilized over the past three months.
Total call volume along with approximate input and output token counts. Even when relying on vendors for operations, these metrics can always be retrieved. Being told they cannot provide these numbers is itself an operational red flag.
With actual usage figures in hand, you can calculate on the spot exactly how price revisions affect your organization. Without them, every price cut passes by as mere news that "things got cheaper," while contracts and estimates stay frozen. The only side capable of driving change is the one holding the numbers.
Whether you want to organize the cost structure of an AI-enabled system or confirm if your existing agreements reflect vendor price drops, GleamHub is here to assist through our development, AI, and automation consultations. Because optimal configurations vary based on requirements, we provide customized estimates. Please reach out via Inquiries.
Sources
- Advancing the price-performance frontier with GPT-5.6 — OpenAI
- How GPT-5.6 fuses frontier intelligence with frontier efficiency — OpenAI
- OpenAI drops GPT-5.6 Luna and Terra API prices by up to 80% — InfoWorld
- OpenAI Cuts GPT-5.6 Luna API Prices by 80%, Terra 20% — eWeek
- OpenAI Lowers API Pricing for GPT-5.6 Luna and Terra — gihyo.jp