You launched a product review section, or opened a member-to-member community. Everything went smoothly until six months later, when scanning every submission each morning became a specific person's daily chore.
Operations halt whenever that staff member takes time off. Because nobody else knows their decision rules, no one can step in. Furthermore, records of handling user reports sit buried inside that person's inbox. This bottleneck appears with alarming frequency across businesses running user-generated content.
Attempts to automate using commercial moderation APIs run into the next wall: decision categories are predetermined by the provider. Violence, sexual content, hate speech—all necessary, yet rarely where day-to-day troubles lie. You want to stop comparative posts naming competitor products, false claims regarding industry certification standards, or sockpuppet-style reviews, but pre-packaged categories offer no match.
Supplying criteria written in plain text
Released by Mistral on August 4, 2026, Shieldstral brings a different approach to this challenge (Introducing Shieldstral — Mistral AI).
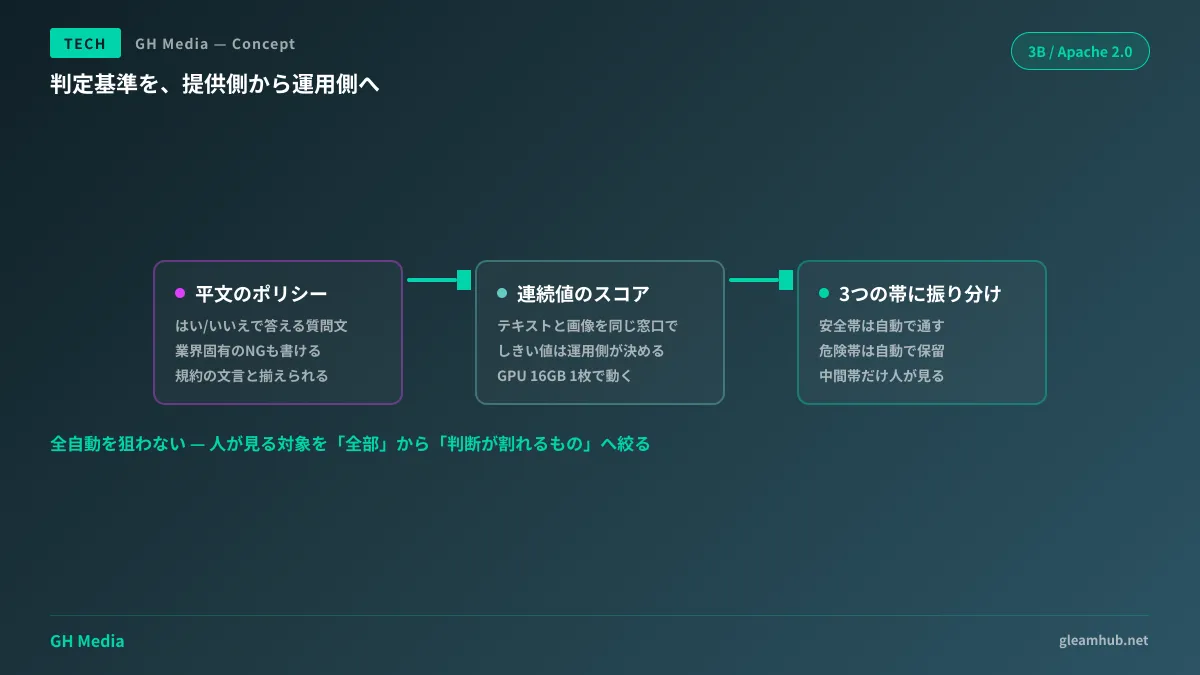
It is a 3-billion-parameter (3B) multimodal safety classification model licensed under Apache 2.0, with weights distributed on Hugging Face. Its notable feature lies not in its size, but in the classification framework itself.
While conventional guardrail models are designed around classification into fixed categories, Shieldstral takes plain-text policies at inference time. Developers pass evaluation context, yes/no policy questions, and target content. Targets can be prompts alone, responses alone, prompt-response pairs, or images accompanied by text.
The model interprets "yes" and "no" logits, converting them into continuous safety scores. This means applications can define their own thresholds. You can adjust operations dynamically—whether enforcing strict rejections or auto-blocking only high-confidence violations while flagging borderline cases for human review.
In terms of performance, it matches text safety benchmarks of models up to seven times its size and is reported to establish new standards in multimodal moderation. Hardware requirements call for a single 16GB NVIDIA GPU.
Where the difference between fixed categories and adaptable policies matters
Comparing how this distinction impacts real-world workflows yields the following breakdown:
| Fixed-category models | Adaptable-policy models | |
|---|---|---|
| Changing criteria | Waiting for provider updates | Rewriting prompt questions |
| Industry-specific violations | Often impossible to express | Describable in plain text |
| Explaining moderation rationales | Category name only | The supplied policy serves directly as justification |
The third row pays off immensely in operations. When posters ask why their submission was taken down, stating "our platform prohibits unqualified claims regarding certification" holds up far better than saying "classified as hate speech." In essence, moderation criteria align directly with your terms of service.
Do not assume machines will handle everything
At this point, expectations should be calibrated realistically. Attempting to fully automate moderation almost always fails. Deleting legitimate content through false positives drives users away, while loosening rules defeats the purpose.
The truly practical approach is using it to reduce human review volume.
- Score all submissions, and automatically pass clearly safe content. This accounts for the vast majority of volume.
- Automatically hold clearly harmful submissions, stopping them prior to publication.
- Have humans review only the remaining borderline tier.
Under this structure, morning reviews shift from "inspecting everything" to "reviewing only ambiguous edge cases." The biggest transformation is turning an ad-hoc chore dependent on a single individual into a process managed transparently through numeric thresholds.
The advantages and trade-offs of hosting small models locally are covered in Building a Local LLM Environment with Gemma 4 and Introduction to Microsoft Foundry Local. The adjacent topic of tracking asset origins is summarized in Provenance Management for AI-Generated Content.
Host internally or rely on an API
The availability of open weights does not necessarily mean you should self-host. The decision primarily hinges on two factors:
First, whether submissions can leave your infrastructure. In use cases involving members-only community discussions or internal enterprise data, getting internal approval to transmit raw content to third-party APIs can be difficult. Here, an entirely self-hosted deployment provides immense value.
Second, volume and traffic spikes. If post volumes surge only during seasonal campaigns, pay-as-you-go APIs prove cheaper than sustaining dedicated GPU servers year-round. Conversely, steady daily volume makes self-hosting more cost-predictable.
Either way, what needs deciding first is not infrastructure, but policy text. Articulating what you want to block in plain text is necessary regardless of whether models are used, and that step takes the most time. Comparing current terms of service against customer support moderation logs to translate past manual decisions into explicit rules is the quickest way forward.
Where to start
If manual inspection currently relies on a single person, gathering the past month's enforcement records and categorizing removal reasons is the best first step. That taxonomy serves directly as your policy draft. Categorization typically reveals only three to five core violations, clarifying immediately what can be handed off to machines.
GleamHub offers guidance on operational workflows for content platforms and integrating automated classification through our custom development, AI, and automation consultations. Because optimal setups vary by post volume and data sensitivity, we provide tailored estimates. Please reach out via our Contact Us page.