
When evaluating AI agent adoption, one explanation invariably comes up: "Dangerous actions like deleting files or executing commands require human approval each time, so it is safe." This gets internal approval passed. And once approved, this premise is something nobody ever verifies.
Can humans truly stop dangerous actions at an approval screen? A browser game released in late May 2026 by Belgian developer Alex Wauters made this exact question measurable. Players are shown successive requests from an AI coding agent and choose whether to approve or reject them. Blocking safe requests deducts points, and letting dangerous requests pass also deducts points.
The collected data encompassed over 40,000 plays and 409,000 approval and rejection decisions. According to statistics published by Scale X, the results were as follows.
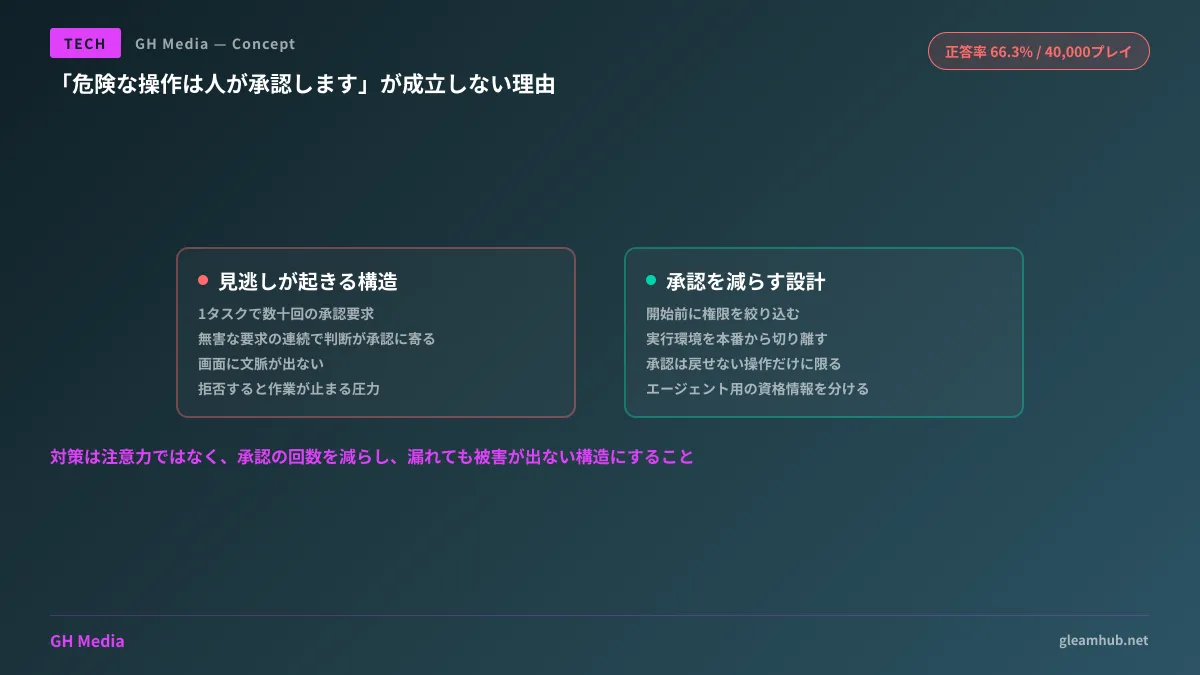
- The average accuracy rate was 66.3%. In other words, one out of every three threats was missed
- 32.9% of sessions ended with a net negative score
For one-third of players, the penalties from allowed threats and blocked safe operations exceeded the points gained from correct decisions. That means the outcome was worse than doing nothing at all.
The root cause of missed threats lies in structure, not attentiveness
Dismissing these numbers as a lack of focus reduces countermeasures to mere pep talks. In reality, the reasons approval screens fail lie in their design.
The first factor is volume. An agent requests dozens of actions within a single task, most of which are harmless. When a single dangerous item is slipped in after a series of harmless requests, human judgment is already biased toward approval. An article in The Register also points out this pattern, where high noise creates fatigue, and fatigue leads to incidents.
The second factor is the lack of context. What appears on the screen are fragments of commands and operations, with no explanation of why they are needed. Judging whether "this rm is correct" requires knowing what the agent did up to that point, but approvers rarely track that history.
The third factor is the cost of rejection. If you stop it, the work halts, the agent searches for another method, and it asks for approval again. There is constant pressure that leaning toward safety prevents progress. The game's design penalizing users for stopping safe actions was meant to replicate this reality.
Designing toward fewer approvals
The countermeasure is not to "approve more carefully." It is to reduce the number of approvals itself and structure the system so that failed approvals cause no harm. From an implementation perspective, this works best in the following order.
- Narrow down permissions granted to the agent before the task starts. Instead of demanding runtime decisions, run it with permissions that cannot perform dangerous operations in the first place. The mindset of granting only what is needed for the required duration is covered in Moving Away From Standing Access Toward JIT Access
- Isolate the execution environment from production. Let the agent interact directly only with a working copy, applying changes to production through a separate path. This ensures that even if one approval slips through, the damage does not reach production
- Distinguish between reversible and irreversible actions. Allow reversible operations to pass without requiring approval. Limit approval prompts strictly to irreversible actions such as external transmissions, deletions, and permission changes
- Separate credentials used by agents from human accounts. Running them under shared accounts prevents post-incident auditing of who did what. Steps for organizing this are outlined in Taking Inventory of Non-Human Identities
The third measure is effective because it drops the number of items appearing on approval screens into single digits. If approvals per task drop from 50 to 3, those 3 will actually be read. The 66.3% accuracy rate is a figure that includes instances where users clicked through without reading.
Two questions clients ordering systems should ask
When contracting out agentic workflows, if the specification states that "dangerous actions require approval," ask the following two questions.
First, how many approvals are expected to occur per task? If they cannot provide a number, approvals have not been designed as a safety mechanism. Answering "as needed" practically means unlimited.
Second, what happens when an approval slips through? If the response is "we assume none will slip through," that is an architectural void. You must not build systems on the premise that nothing slips through when measurements show one in three does.
Furthermore, human inattention is not the only path that bypasses approval screens. There is also a pathway where instructions are embedded in external documents or web pages read by the agent, prompting the agent itself to request dangerous actions as legitimate tasks. Defending against this requires a separate approach, which we cover in Defending Against Indirect Prompt Injection.
What to do next
If you are already piloting agents, open your approval logs from the past week and count the number of approvals granted versus the number where you can honestly say you read the contents. The difference between these two figures is the part that is currently failing to function as a safety mechanism.
If that gap is large, what you need to increase is not vigilance, but designs that do not demand approvals. Whether to begin by narrowing down permissions or isolating environments depends on your data and workflows.
If you would like to consult on permission design or execution environment isolation when integrating AI agents into operations, we handle requests through GleamHub's Development, AI, and Automation Consultations. Because optimal architectures vary depending on target workflows and the data handled, we provide individual quotes. Please reach out via Contact Us.
Sources
- Humans missed 1 in 3 threats approving AI agent commands across 40,000 plays — Scale X
- Humans in the loop miss a third of dangerous AI coding agent requests — The Register
- Suffering from Agent Permission Fatigue? Find out your high score — Scale X
- AI Agent Approval Prompts Are Not Authorization — Blake Crosley




