
Requirements definitions for enterprise systems almost always include "exporting list view data to Excel." If you ask whether CSV is acceptable, the answer is usually no: column widths are not aligned, dates turn into numbers, and it cannot be forwarded directly to clients. In many cases, exporting to Excel effectively means "exporting in a state ready to print and circulate immediately."
Selecting the library to implement this single requirement has become increasingly difficult over the past few years.
A former staple is no longer installed standardly
For a long time, SheetJS (package name xlsx) was the standard library for handling Excel files in JavaScript. It supported a broad range of reading and writing features and had extensive Japanese-language documentation. It was invariably the first candidate considered.
However, SheetJS stopped distributing via the public npm registry and transitioned to distribution through its own CDN (cdn.sheetjs.com). As a result, xlsx on npm is stuck at 0.18.5, remaining unchanged from its release several years ago. Updates containing security fixes are in newer versions on the CDN side, so running standard npm install xlsx from npm installs outdated code.
In practical work, this manifests as an obstacle when flagged by dependency vulnerability scans. When an alert demands an update, no update destination exists on the registry. Reinstalling requires pointing directly to a CDN tarball URL, but that pattern often conflicts with corporate proxy configurations, CI environments, and audit mechanisms. Even if resolved technically, it adds another administrative approval step. In custom development, this single hurdle places a surprisingly heavy burden on projects.
Even if you opt for ExcelJS, another popular standard, the fact remains that its dependency tree is quite large. For a single business capability—Excel export—the structure forces dozens of additional packages into scope for security audits.
Zero-dependency options for reading and writing
In August 2026, a library named hucre reached v1.0.0. Written in pure TypeScript with zero package dependencies, it is a spreadsheet engine supporting reading and writing for XLSX, CSV, and ODS. It includes a built-in calculation engine that evaluates cell formulas and handles standard Excel functions. It runs across Node.js, Bun, Deno, and the browser.
From an evaluation standpoint, what proves most valuable is not merely its functionality, but the fact that you only need to audit a single package. Zero dependencies means that whatever vulnerability scanners inspect is confined entirely to the one package you chose, greatly simplifying supply chain risk assessments. Now that installation scripts on npm are treated as realistic attack vectors, the sheer count of dependencies has become an active decision factor. We also covered this context in Countermeasures from the Package Manager Side.
On the other hand, you must account for the fact that this library has only just reached v1.0. A v1 release signifies a commitment to public API stability; it is not proof of an established track record. Whether to base an enterprise system intended for five years of operation on it depends on the distinctions outlined in the next section.
Required tools depend on what needs to be output
The requirement to "export to Excel" actually lumps together three distinct needs under the same phrase. Without separating them, you cannot settle on a library.
| Actual requirement | What is required | Weight of selection |
|---|---|---|
| Data exchange (importing into other systems) | Values must be accurate; formatting does not matter | Light; CSV can often suffice |
| List downloads (for user processing) | Types must stay intact; dates remain dates | Moderate; minimal dependencies will suffice |
| Formatted business reports (printed or sent directly) | Borders, merged cells, print areas, headers, footers | Heavy; requires a proven track record for styling and layout |
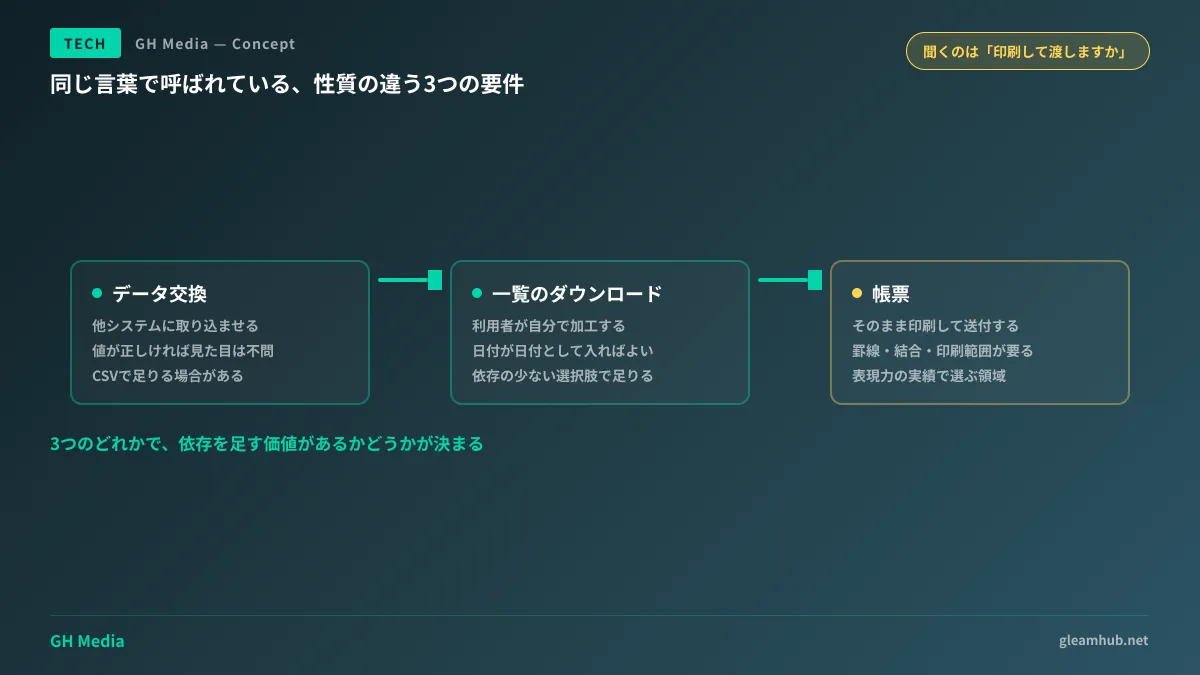
When clients ask for Excel, what they usually have in mind is the third row. The moment you attempt to implement that third row, differences in library styling capabilities become decisive: border styling, merged cells, auto-fitting column widths, and page break positions for printing. If that degree of fidelity is required, it is often faster either to choose an established option or to reconsider the design entirely by outputting a PDF instead of Excel.
Conversely, for the first and second rows, zero-dependency options are entirely practical. In fact, saddling a system with a large dependency tree simply for basic data exports results in higher lifecycle maintenance costs across the operating period.
Deciding where to implement generation
The arrival of zero-dependency libraries that run in browsers introduces another shifting decision point: whether to generate Excel files on the server or in the browser.
Generating in the browser consumes no server resources or memory. In operational workflows where multiple users simultaneously download reports with tens of thousands of rows, this difference is substantial. However, because all data needed for generation must be transmitted to the browser, you must ensure you are not passing columns hidden from the screen or fields restricted by permissions. Skipping this check on lists containing personal data risks serious incidents.
When generated on the server, output content can be assembled while strictly filtered by permissions. It also makes it easier to capture "who exported what" in audit logs. In enterprise systems, preserving this audit trail is often far more critical than raw performance. Approach this decision based on data sensitivity rather than performance.
Do you really need to export to Excel in the first place?
Finally, consider questioning the requirement itself. The reason "export to Excel" frequently enters requirements is that the system cannot perform the necessary aggregations internally. Users export Excel files to build formulas and aggregate figures, which another colleague then manipulates further. If this chain is occurring, what should be built might not be an Excel export, but the aggregation feature itself.
Criteria for determining how much Excel workflow to retain and what to absorb into the system are summarized in When to Transition Excel Workflows to Systems. For practical approaches to migrating existing Excel assets to spreadsheets, refer to Migrating Tables and Pivot Tables Without Rebuilding.
What to do next
When an Excel export requirement arises, ask the client which category in the table above it represents. Asking "Will this be printed and handed to clients?" usually yields an immediate answer. Once that is clear, your library selection narrows down automatically.
If you maintain a system already using xlsx, verify whether it was installed from the npm registry or a CDN. If installed from npm, that version belongs to a line whose updates have halted. While not an immediate emergency, you need to understand that the architecture cannot readily respond if a vulnerability is reported.
We consult on reviewing existing system dependencies and establishing design policies for reporting and export features through GleamHub's Development, AI, and Automation consulting services. Because optimal architectures depend on intended usage and data sensitivity, please consult with us individually. Reach out via Contact Us.
Sources
- hucre — Zero-dependency spreadsheet engine (GitHub)
- Hucre - Spreadsheet I/O for TypeScript
- Release of "hucre" v1.0.0, a Zero-Dependency TypeScript Spreadsheet Engine — gihyo.jp
- SheetJS
xlsxmigration — SheetJS CDN - npm package with 1.4M weekly downloads ditches npmjs.com for own CDN — BleepingComputer


